 AI / ML
Understanding Positional Embeddings in Modern LLMs
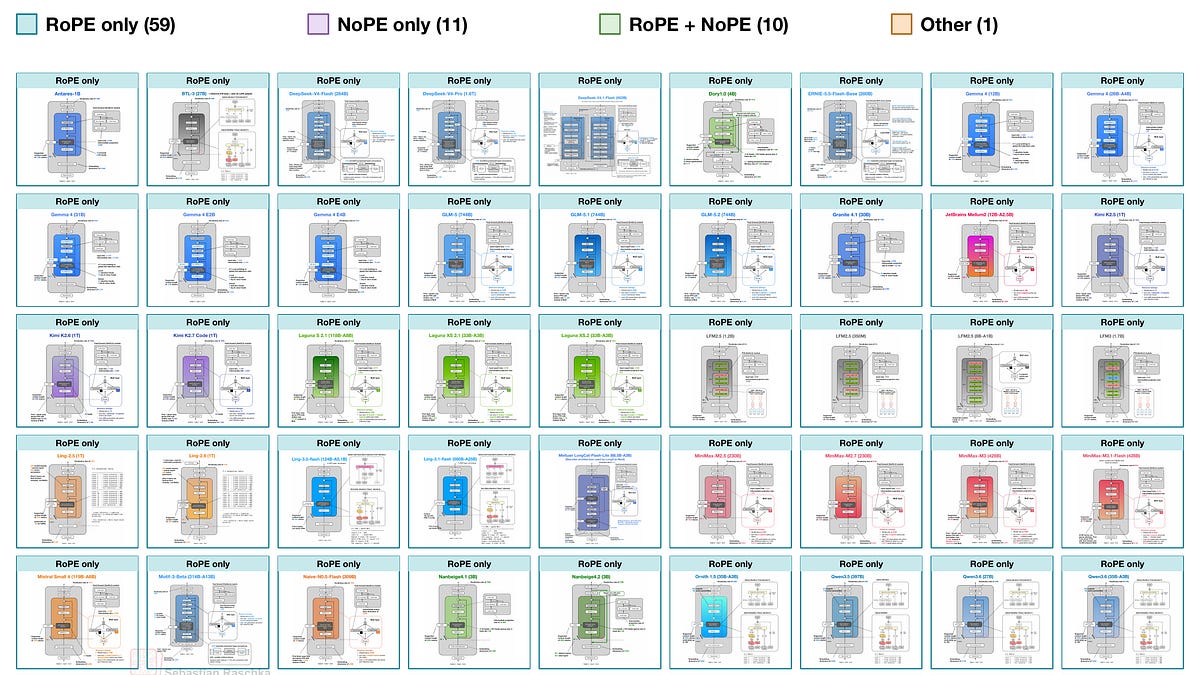
The article explains the encoding and processing of token position information in Large Language Models (LLMs) through classic and contemporary methods, including Relative Positional Embeddings (RoPE) and its comparison to absolute embeddings used in GPT. It provides a visual guide, mathematical explanations, and a small PyTorch implementation, and discusses how modern architectures adapt or omit explicit positional encodings. The article assumes some familiarity with basic LLM architectures and is intended as a follow-up to a previous article on building a language model from scratch. It is aimed at readers who want a deep technical understanding of LLMs and their positional information methods. The article is part of a series on LLM architecture trends, and the author plans to write a follow-up article on the latest trends in the field. The article is very technical and may be too detailed for some readers, but it provides a foundation for future articles on the subject.
Read the full article at magazine.sebastianraschka.com →