 AI / ML
Show HN: Parsimony – an open-source benchmark for how much code AI models add
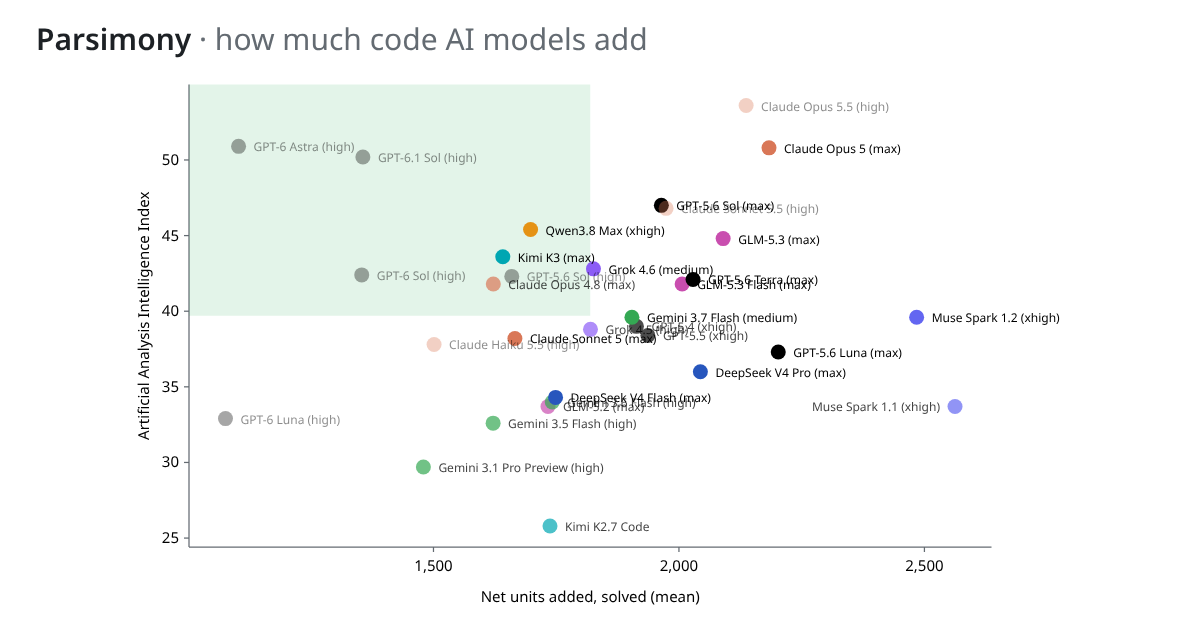
Parsimony is an open-source benchmark that measures the amount of code added by AI models, rather than just their solve rate or token output/cost. This is important for long-term projects, as excessive code can make a codebase harder to work with. The benchmark takes existing patches from DeepSWE, SWE-bench Verified, and SWE-bench Live, and counts 'coding units' such as statements, calls, names, and literals. Deleted code is subtracted, so the benchmark measures net units. GPT-6 and Claude 5.5 were tested on 3-10 tasks, and the results are included in the benchmark. The project is open to feedback and contributions, especially public patch exports for newer models.
Read the full article at parsimony.lasu.dev →